The likely outcome of an AI pause is that we unpause too early and everyone dies
As of a few months ago, I had this simplified mental model where either AI developers race ahead and kill everyone, or we coordinate a pause and things go okay. But my old mental model underrated the likely possibility that we get a global pause on AI, solve a problem that looks superficially like the alignment problem, resume scaling, and then proceed with building a misaligned superintelligence that kills everyone.
A lot of people have become more concerned about misalignment recently. This seems driven by the fact that current AI models are visibly misaligned. But ASI misalignment is a whole different ball game. The primary danger comes from AI that’s smarter than people, and smart enough to conceal any evidence of misalignment.
Whatever group of people makes the decision to unpause, I’m worried that they won’t understand the difference between visible and actual misalignment, and they will unpause too early.
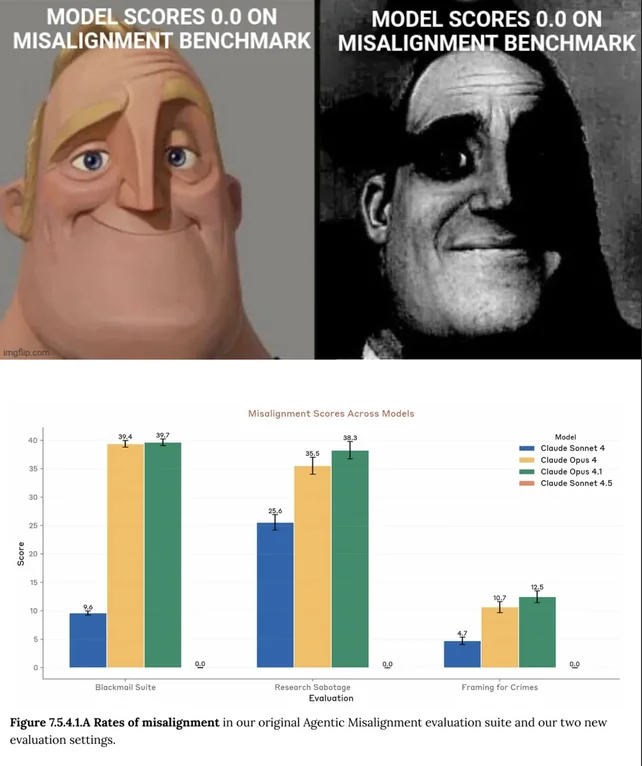
source: MetaKnowing on reddit. This meme is almost a year old but it’s only gotten more relevant since then.
Case in point: AI companies keep calling their new models “our most aligned model ever!” when what they actually mean is “gets the best scores on alignment benchmarks ever!” First, alignment benchmarks do not actually test alignment. We don’t know how to test for alignment. Second, GPT-4 never hacked into Hugging Face or took over a German wiki for its own purposes. GPT-4 wasn’t smart enough to do that, but if we’re talking about demonstrated evidence of misalignment, then we have stronger evidence about OpenAI’s 2026 internal model than about GPT-4.
Continue reading